Grok 4.6 Is Here: Long Running Agents and Upgraded Coding
If you have been keeping an eye on AI developments, you know that building a conversational assistant is one thing, but creating an agent that can reliably work over hours or days is a whole different challenge. Today, xAI officially released Grok 4.6, bringing a major upgrade focused on long-running agents, complex reasoning, and ambitious visual app creation.
Whether you are building full-stack web applications, refactoring complex codebases, or working through technical research, Grok 4.6 is designed to stay on task across multiple steps. Let us dive into what makes Grok 4.6 such an exciting release, how it performs on top benchmarks, and how you can start trying it today.
What Is Grok 4.6?
Grok 4.6 is the latest flagship model from xAI, building directly on Grok 4.5. While previous iterations focused on conversational speed and retrieval, Grok 4.6 pivots sharply toward agentic workflows. That means handling multi-step tasks requiring planning, execution, self-correction, and visual output.
Instead of giving short code snippets, Grok 4.6 takes a high-level prompt, researches unfamiliar library APIs, structures application architecture, writes code, and inspects its own work for bugs before finishing.
Key Improvements in Grok 4.6
- Sustained Agentic Trajectories: Maintains context across long execution chains for multi-file projects.
- Single-Pass Visual Building: Creates complete visual layouts and interactive user interfaces from a single prompt.
- Built-In Self-Verification: Actively tests its own output before moving forward, catching errors early.
- Frontier Benchmark Gains: High score increases in software engineering and agentic evaluations.
Long-Running Agents and Deep Coding
A persistent hurdle in AI assisted development has been context drift, where models forget early constraints in large conversations. Grok 4.6 addresses this head-on with improved context maintenance during agentic execution.
In practical testing across STEM tasks, kernel optimization, CAD design, and web development, Grok 4.6 demonstrated an ability to navigate deep technical problems step by step. If a compile check fails or a test breaks, the model inspects the error trace, adjusts its plan, and retries until resolved. This self-correction loop makes Grok 4.6 a highly reliable development partner.
Single-Pass UI and App Generation
Beyond code logic, Grok 4.6 brings a strong leap in visual design implementation. Given a broad idea for a web tool or dashboard, the model establishes layout structure, styling details, and component hierarchy in a single pass.
Rather than starting with plain unstyled text, developers receive a visual foundation immediately. From there, you can iterate inside your IDE or design environment to refine features and add backend endpoints.
Under the Hood: Training Grok 4.6
How did xAI achieve this jump in agentic performance? The team combined several key training innovations:
First, Grok 4.6 underwent a longer supplemental pre-training run compared to Grok 4.5, incorporating high quality engineering data alongside synthetic data focused on technical reasoning.
Second, xAI used Grok 4.5 to generate fine-tuning trajectories across agent harnesses, coding domains, and scientific workflows, using automated checks to filter out low quality traces.
Finally, Grok 4.6 received extensive reinforcement learning in domain-specific environments, including web design, CAD modeling, system optimization, and realistic engineering sandboxes.
Benchmark Performance: How Does Grok 4.6 Stack Up?
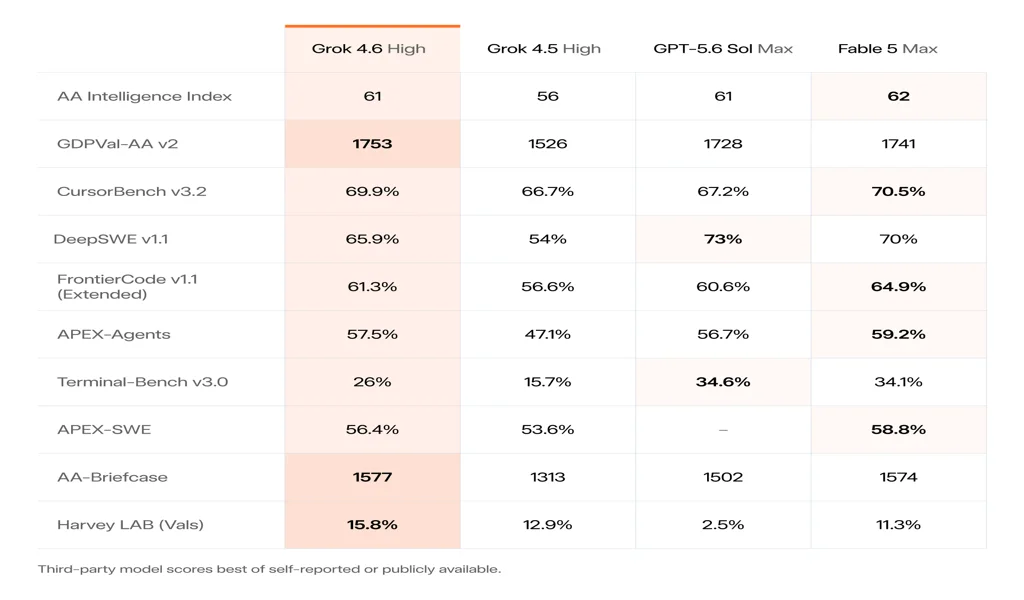
xAI published comprehensive benchmark comparisons alongside the release, pitting Grok 4.6 against Grok 4.5 and competing models:
- AA Intelligence Index: Grok 4.6 scored 61, matching GPT-5.6 Sol Max (61) and beating Grok 4.5 (56).
- GDPVal-AA v2: Grok 4.6 earned a top score of 1753, leading the evaluation field.
- CursorBench v3.2: Reached 69.9% accuracy, up from 66.7% in Grok 4.5.
- DeepSWE v1.1: Jumped to 65.9%, demonstrating a huge leap over Grok 4.5 at 54%.
- FrontierCode v1.1: Scored 61.3%, showing steady gains in complex coding challenges.
Safety and Responsible Deployment
As AI agents gain autonomy, security is paramount. xAI updated safety safeguards specifically calibrated for agentic capabilities.
The safety framework supports legitimate technical work like vulnerability patching, security research, and engineering design, while protecting against misuse. Evaluation included xAI's broadest testing suite to date, plus third-party red teaming.
Pricing, Availability, and Special Promotions
Grok 4.6 is available immediately across multiple tools:
- Cursor & Grok Build: Available today inside Cursor and Grok Build, featuring 2x included usage during the first week.
- Developer API: Priced at $2 per million input tokens and $6 per million output tokens via the SpaceXAI API console (fast variant at 2x price).
- Partners: Integrated into OpenRouter, Vercel, and Cloudflare.
Final Thoughts: Ready to Try Grok 4.6?
Grok 4.6 represents a practical step forward for developer AI tools. By prioritizing agent reliability, single-pass UI design, and self-verification, xAI has built a model that feels like an active engineering collaborator.
Whether spinning up a new frontend prototype or resolving a stubborn bug, Grok 4.6 is ready to help. Try it in Cursor or Grok Build to claim your first week bonus usage!